Custom LLM Integration

What It Is
What is Custom LLM Integration?
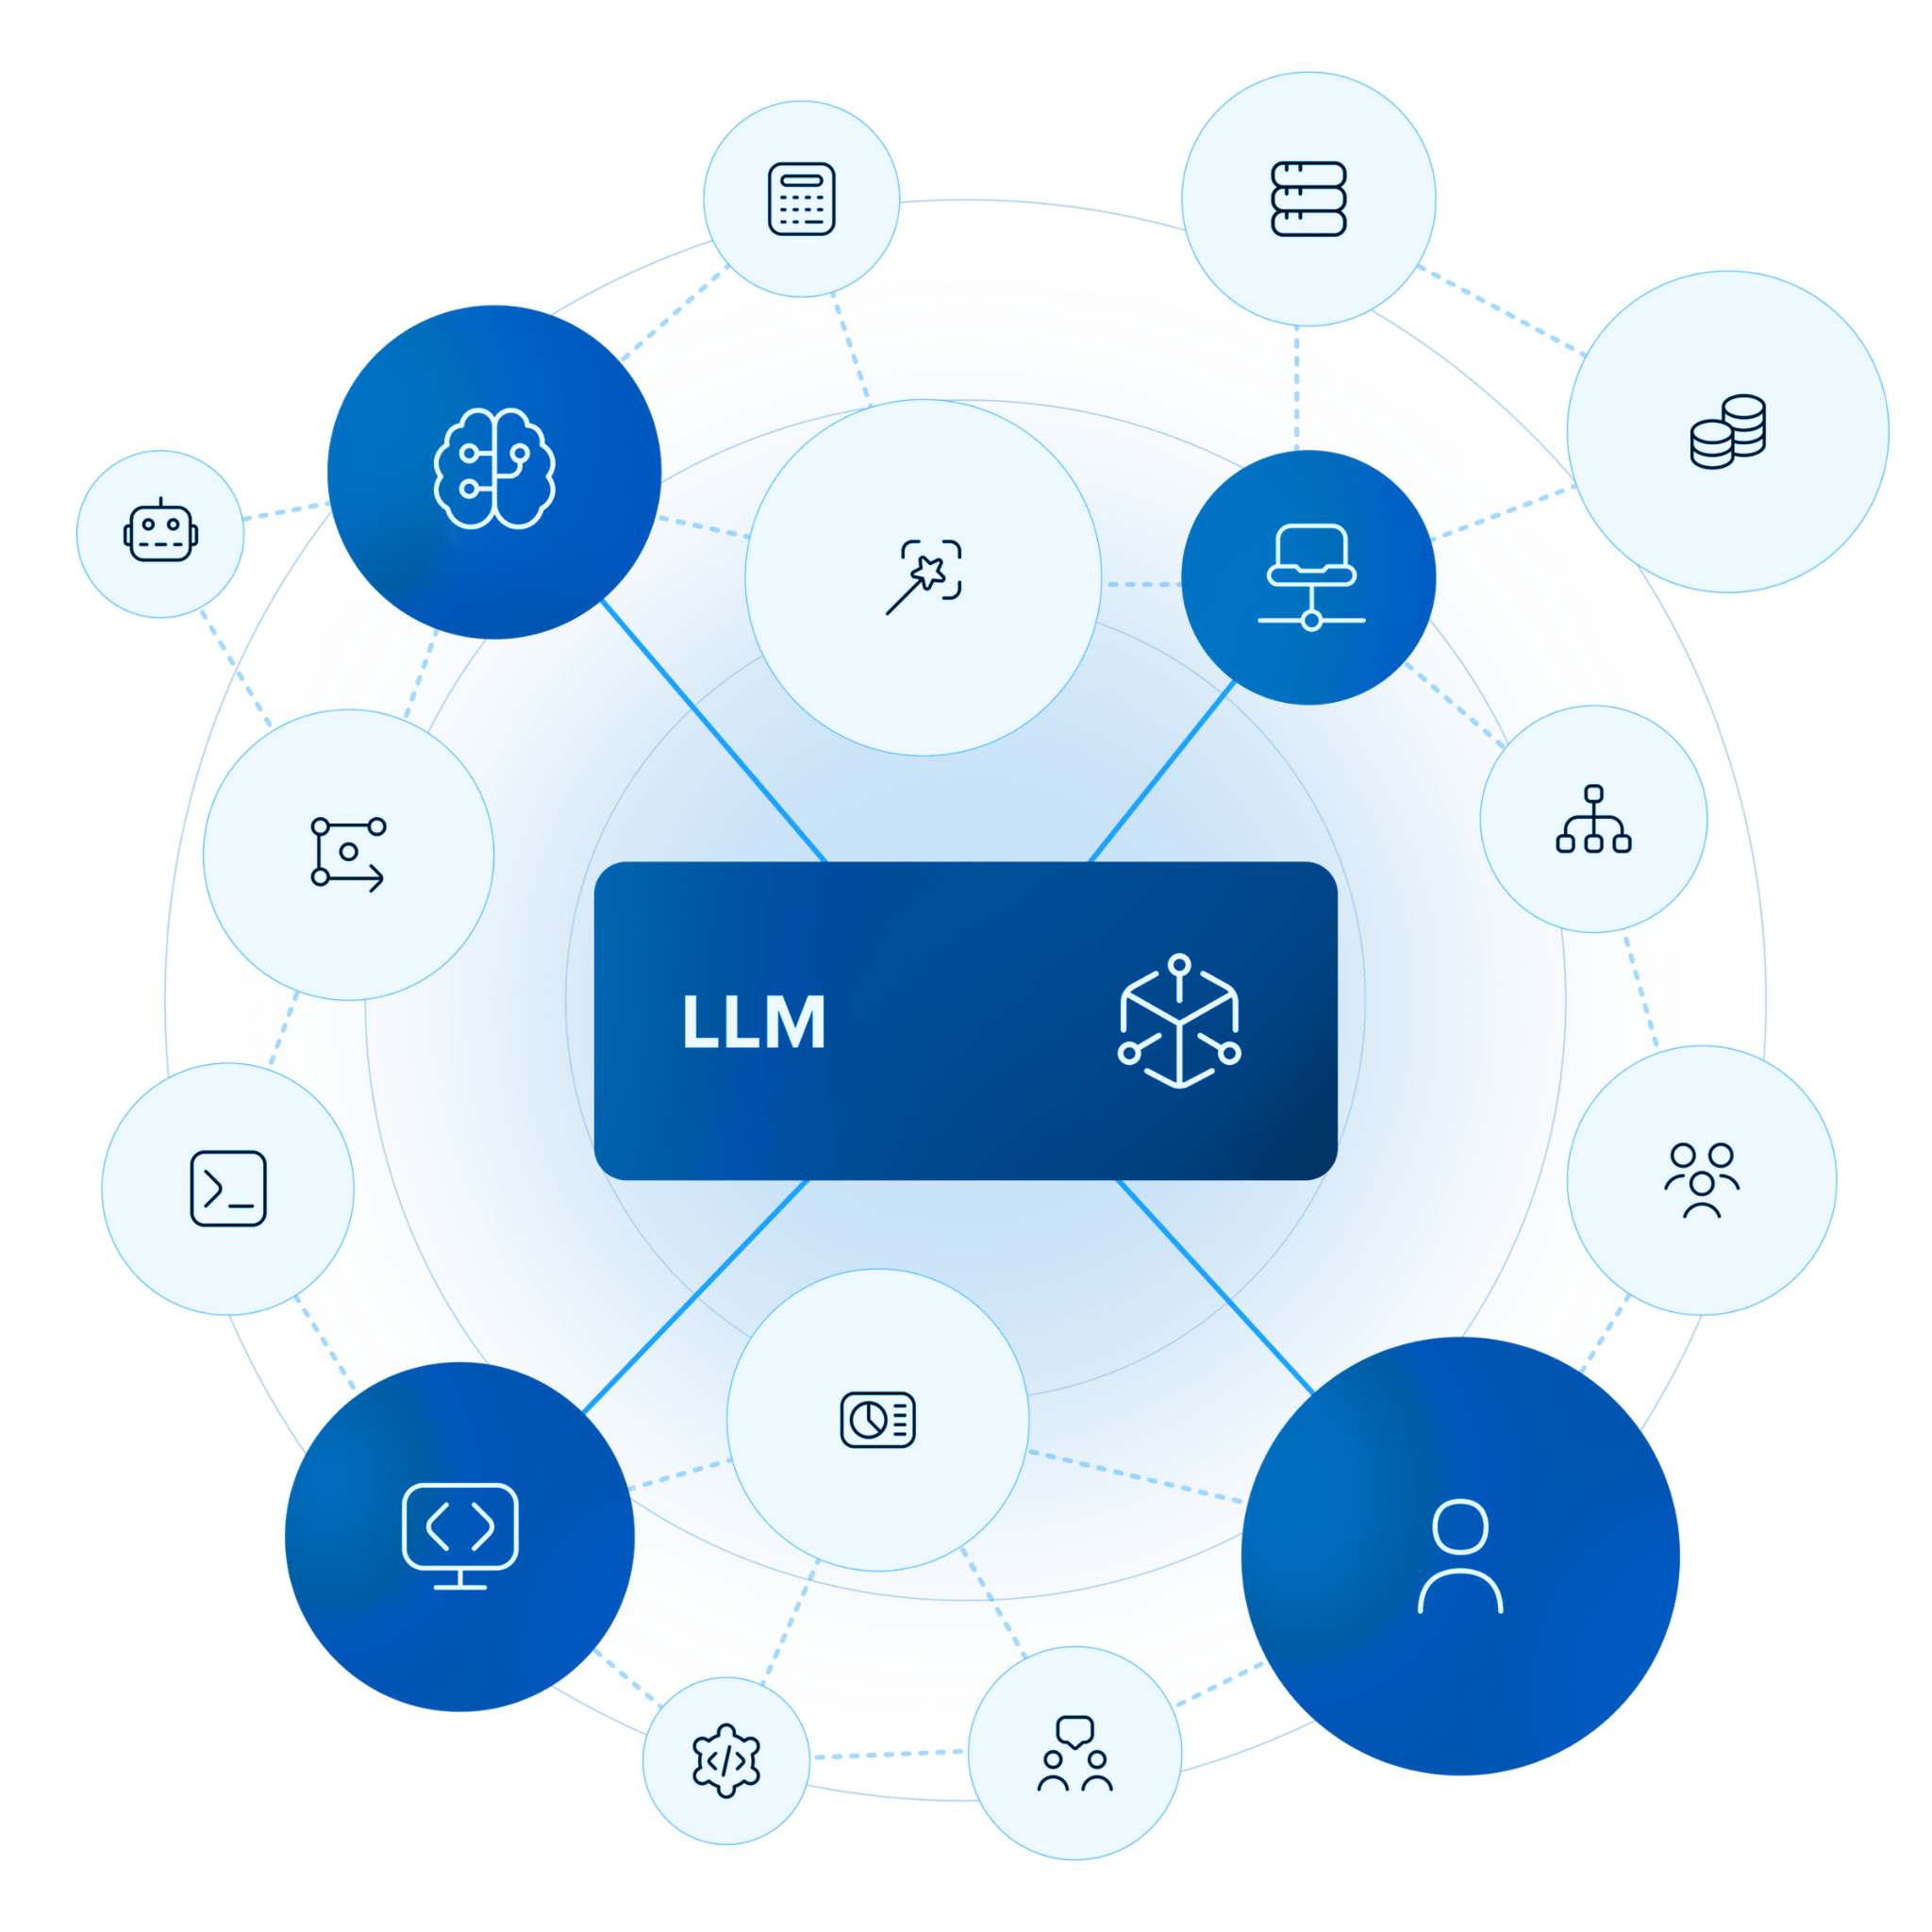
Custom LLM Integration means embedding a tailored Large Language Model directly into your applications and AI agents. We fine-tune the model on your own data, connect it through APIs your engineers can actually work with, and deploy it for the specific jobs you need — natural language understanding, generation, extraction, and decision support.
RAG As a Service
Types of custom LLM integration
Six approaches. Which one fits depends on your data sensitivity, latency budget, and how deep the model needs to sit inside your product.
Fine-tuning
Adapt a pre-trained model with your domain data so it learns your terminology, tone, and the edge cases a general model keeps getting wrong.
API wrappers
Seamless integration through RESTful APIs and SDKs, with retries, rate limiting, streaming, and cost controls already handled in the layer.
Modular plugins
Plug-and-play components for agent frameworks like LangChain or LlamaIndex, so adding a capability is enabling a module, not a rebuild.
Hybrid models
Combine several LLMs behind one interface and route each request to the right one — a small fast model for classification, a frontier model for hard reasoning.
On-premise
Self-hosted integrations with open-weight models inside your VPC or data centre, for teams whose policy says the data cannot leave the building.
Edge deployment
Quantized models running close to the user or on-device, for real-time agents where a round trip to the cloud is already too slow.